
Engineering
Shadowing route providers without production impact
Aug 11, 2025
At Cabify, we rely heavily on external route providers to deliver the most accurate and efficient navigation experiences. Whether it’s estimating journey durations or calculating distances between pickup and drop-off points, our routing infrastructure needs to be both fast and reliable.
But how do we safely compare different routing providers to validate accuracy, performance, and stability—without affecting our production environment?
In this post, we’ll explore how we use shadow requests in Go to parallelly evaluate external route APIs. This approach enables us to test providers under real-world traffic conditions while keeping the production path untouched. We’ll also cover how we collect deviation metrics to monitor the differences between actual and shadowed responses.
What are shadow requests?
Incorporating a new route provider or validating changes in existing ones can be risky if tested directly in production. Shadow requests solve this by duplicating real user requests and sending them to the new provider in parallel. This fire and forget approach ensures the main execution flow remains unaffected. Crucially, these shadow requests:
- Do not block or delay the main request flow.
- Do not affect the response returned to the user.
- Allow for real-time performance and accuracy benchmarking.
This makes shadowing a powerful strategy for continuous validation and experimentation without any user-facing risk.
How it works in our Go code
Using the decorator pattern to extend provider logic
In our routing system, we apply the Decorator Pattern to enhance the behavior of existing route providers without modifying their internal logic. This is achieved by wrapping the original routes.Provider with a custom provider implementation that adds shadowing capabilities.
type provider struct {
    actual   routes.Provider
    shadowed routes.Provider
    ...
}
The NewProvider function takes two routes.Provider instances:
actual: the main provider used for production traffic.shadowed: the secondary provider used only for shadowing and comparison.
Our custom provider struct implements the same Route method signature as the original provider interface:
func (p *provider) Route(ctx context.Context, request routes.Request) (response routes.Response, err error) {
   // custom shadow provider logic
   if p.tryAcquireWorker() {
      // create a buffered channel to send the main response
      respCh := make(chan responseWrapper, 1)

      // defer the sending of the response to the channel
      defer func() {
         respCh <- responseWrapper{response, err}
         close(respCh)
      }()

      // use a goroutine to shadow the request and report metrics
      go func() {
         defer p.releaseWorker()
         p.shadowRequestReport(ctx, request, respCh)
      }()
   }

   return p.actual.Route(ctx, request)
}
This means we can transparently replace any existing provider with our decorated version, and it will still behave the same from the caller’s perspective—except now it also sends shadow requests in the background and logs metrics.
The beauty of the Decorator Pattern here is:
- ✅ It adds logic (shadowing, metrics, logging) without touching the actual provider code.
- ✅ It is interchangeable with any routes.Provider, so it integrates seamlessly.
- ✅ It makes it easier to compose behaviors and isolate concerns.
This pattern helps us maintain clean code while enabling powerful instrumentation features safely and independently.
How shadow requests works behind the scenes
flowchart LR
   A["Route request"] --> B["Call actual provider"]
   A --> F{"Max workers available?"}
   B <--> G["Return response to user"]
   G -.-> H["Send main response to channel"]
   H -.-> E["Collect deviation metrics"]
   F -- Yes --> D["Send shadow request (non-blocking)"]
   D --> E
   F -- No --> C["Discard shadow request"]
   style A fill:#e0e0ff,stroke:#333,stroke-width:1px
   style B fill:#e0e0ff,stroke:#333,stroke-width:1px
   style G fill:#e0e0ff,stroke:#333,stroke-width:1px
   style H fill:#f9f,stroke:#333,stroke-width:1px
   style D fill:#f9f,stroke:#333,stroke-width:1px
When a new routing request arrives at our service, we process it in two distinct paths—one that fulfills the user request (the main path), and another that evaluates a secondary provider for comparison (the shadow path).
Here’s how we handle it:
- Main Request First
The request is always sent to our primary (or “actual”) route provider. This is the response that powers the user experience—fast, reliable, and unaffected by any testing we may be doing in the background. - Shadow Request in Parallel
At the same time, if system resources permit, we trigger a second request in the background. This is sent to a “shadow” route provider—a candidate we want to evaluate under real conditions. This happens asynchronously, meaning it runs in the background and never delays or interferes with the main request. - Safe Concurrency Control
To avoid overloading the system, we use a worker pool that limits how many shadow requests can run concurrently. If no worker is available, we simply skip the shadow request and move on—no impact, no risk. - Compare and Measure
Once both responses are available, we compare key metrics like distance, travel time, and traffic estimates. These comparisons are reported via internal observability tooling so we can spot any major deviations. - Transparent and Resilient
Even if the shadow provider fails or behaves unexpectedly, users are never affected. The system is built to catch errors gracefully, isolate them, and continue serving production traffic normally.
This approach lets us test new routing APIs in production—at scale and with confidence—while still delivering the performance and reliability our users expect.
Implementation considerations
To safely handle shadow requests in Go, we follow a few idiomatic concurrency practices:
- Buffered channels are used to share the main provider’s response with the shadow routine. This ensures that the shadow request can run independently without blocking the main execution flow.
- A new context with timeout is created for each shadow request. This keeps them bounded and avoids long-running go routines if the shadow provider is slow or unresponsive.
- A panic recovery mechanism wraps the shadow routine to prevent crashes from propagating beyond their scope.
Measuring the Differences: Deviation Metrics
To understand how well a shadow route provider performs compared to our production provider, we capture deviation metrics on every paired request. These metrics help us quantify how “off” the shadow provider is in real-world conditions without ever affecting the user experience.
What we measure
We focus on three core metrics:
-
Distance deviation How much longer or shorter the shadow provider’s route is compared to the actual one. Formula:
(shadowDistance / actualDistance) - 1 -
Duration deviation Compares the estimated travel time between both providers. Formula:
(shadowDuration / actualDuration) - 1 -
Traffic-adjusted duration deviation Evaluates how both providers handle live traffic conditions. Formula:
(shadowDurationInTraffic / actualDurationInTraffic) - 1
These metrics are collected for every request where both providers return valid routes. In addition, we log all route responses whenever both responses are valid and no errors are present.
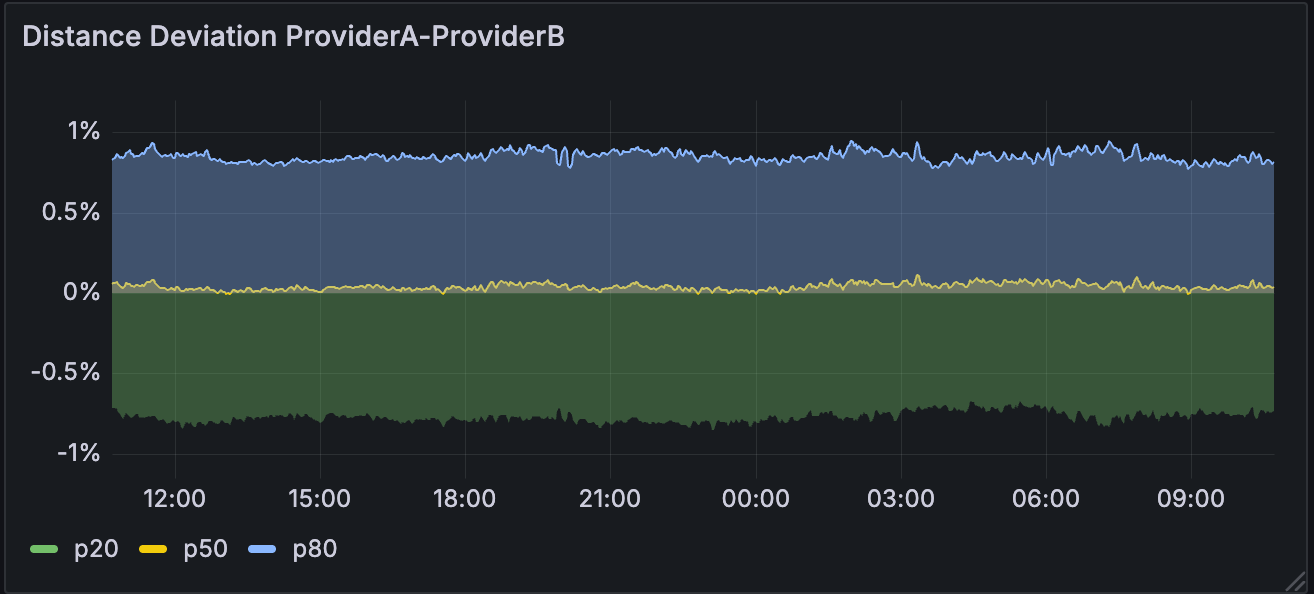 Figure 1: Grafana panel showing time series of distance deviation over time.
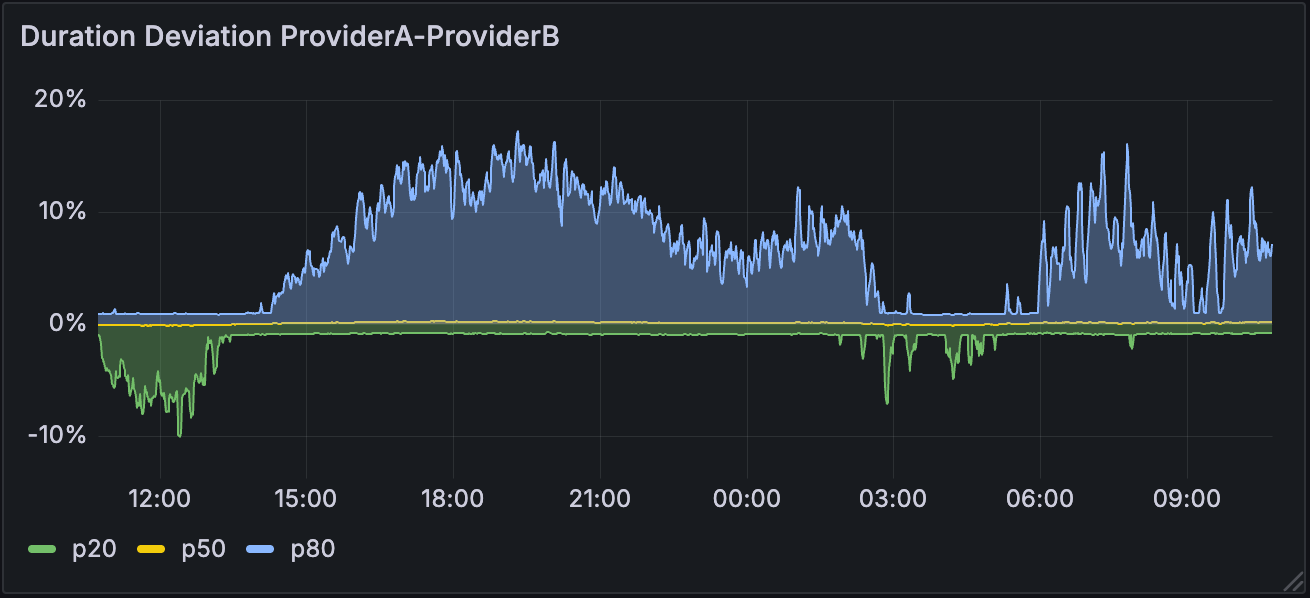 Figure 2: Grafana panel showing duration deviation over time.
Why it matters
- 📈 Visibility: Deviation metrics help us spot consistent over- or under-estimations.
- 🧪 Confidence: We can simulate real production load and validate the shadow provider’s accuracy.
- 🔍 Debuggability: When anomalies arise, we can investigate discrepancies using structured logs and metrics.
All metrics are tagged with contextual labels (e.g., provider name, region, and shadow label) and are exported to our observability platform via OpenTelemetry and Prometheus.
With this data in hand, we can make informed decisions about onboarding, tuning, or discarding a provider—all without impacting the customer experience.
Final Thoughts
Shadow requests have enabled us to confidently test and evaluate third-party route APIs in a production-like environment—without the risks of direct integration. By instrumenting shadow responses and collecting deviation metrics, we continuously validate the accuracy and performance of alternative providers.
This observability-first approach allows us to make informed decisions on provider usage, all while maintaining system safety and user experience.
Got questions or want to learn more? Join us at Cabify Tech and help shape the infrastructure behind mobility at scale.
Hernán Slavich
Software Engineer
Bringing our culture to life through stories—discover it in our blog.
Product
From fragmented workflows to a Connected experience
Oct 14, 2026
Engineering
After the Prompt: How Anyone at Cabify Became a Builder
Oct 07, 2026
Engineering
Stacking
Sep 30, 2026
Engineering
Python Concurrency: Serving ML Without Dying in the Process
Sep 23, 2026
Design
Scaling inclusive design: accessibility as a base
Aug 14, 2026
Culture
The CREP Experience: Building at scale as a fresh graduate
May 28, 2026
Engineering
From Polling to gRPC Streaming at Cabify
Apr 22, 2026
Engineering
From SQL Queries to Real-Time Search
Apr 09, 2026

